

Local models. Inspectable experiments. Ordinary R.
relm runs open-weight models on your machine with no Python, model server or API key. Generate text and constrained JSON, embed documents, and inspect a model’s internal values using ordinary R vectors, data frames and matrices. Its Rust core embeds a pinned, patched llama.cpp; R remains your working environment for statistics, visualization and reproducible research.
Version 0.4.0 adds the complete research workflow:
background generation, token events, live observations, recorded
directions, component projections and base-R graphics, with code and
trace-validation maintenance. See the release
notes. The 0.4.0
release is published, including a verified fresh Mac arm64
r-universe installation. Check packageVersion("relm") and
restart R after upgrading.
This checkout prepares 0.5.0, combining optional Linux CUDA and CRAN source portability. It is not yet a published release or a CRAN-accepted package; see the submission status.
Use r-universe for macOS and Linux builds:
install.packages(
  "relm",
  repos = c("https://vadale.r-universe.dev", getOption("repos"))
)
packageVersion("relm")
r-universe tracks main; check the version before using
the 0.4.0 research features. Prebuilt binaries need no native toolchain.
Source installation needs R >= 4.5, Cargo >= 1.85.0 and rustc
>= 1.85.0 (checked separately), CMake >= 3.28, xz and
a C/C++ compiler. See the installation
guide for source builds and troubleshooting. Development source
additionally supports an explicit
Linux CUDA build; released 0.4.0 binaries are not certified CUDA
builds. Windows CPU source checks passed at PR71; Windows GPU and full
live-file lifecycle parity remain unverified.
Core imports are methods (included with R) and
nanoarrow, which reads spilled traces. glmnet
is optional for probes; uwot and dbscan are
optional demo packages. Optional later and
promises enable async/streaming generation. Application
examples prepare their own separate dependency environments.
The small Qwen model below is approximately 675 MB.
llm_download() verifies the pinned Apache-2.0 model by
SHA256 and reuses a matching cached copy.
library(relm)

path <- llm_download("qwen2.5-0.5b-instruct-q8_0")
m <- llm(path)

llm_generate(m, "The capital of France is", chat = FALSE,
             max_tokens = 8, temperature = 0)

# Embeddings are numerical representations of text: one matrix row per input.
emb <- llm_embed(m, c("cats", "kittens", "quarterly revenue"))
tcrossprod(emb)  # cosine similarities between normalized rows

# Activations are the numerical values inside the model at a selected layer.
tr <- llm_trace(m, "The movie was wonderful.",
                layers = 12, positions = "last", components = "residual")
as.matrix(tr, layer = 12, component = "residual")
llm_tokens() also converts text to token IDs, and
llm_logits() returns the next-token distribution as a data
frame. Capture filters keep traces small; traces over the configured
budget spill to disk and are read a slice at a time. The full 4B-model
spill acceptance on a 16 GB Mac remains an open hardware check.
Pass JSON Schema text to the existing generation function. This example reuses the model loaded above and returns a JSON string:
schema <- '{
  "type": "object",
  "properties": {
    "sentiment": {"type": "string", "enum": ["positive", "negative"]}
  },
  "required": ["sentiment"],
  "additionalProperties": false
}'
llm_generate(m, 'Classify the sentiment of "I loved this film." Return JSON.',
             schema = schema, max_tokens = 64, temperature = 0)
close(m)
Successful calls return complete, validated JSON. Unsupported schemas
fail before generation; incomplete output raises a classed R condition.
The supported profile includes closed objects, bounded strings and
integers, string enums, booleans and null. Arrays, general JSON Schema,
image inputs and nonempty stop sequences are outside this mode. Schema
validation establishes format, not factual correctness. Ordinary text
and image generation retain schema = NULL.
Spark-X2.5-4B is also supported natively through llama.cpp b10828.
Its optional spark-x2.5-4b-q8_0 alias downloads the
official 4.38 GB GGUF. Constrained chat uses Spark’s official
non-thinking opener. Spark activation tracing is
unsupported until an independent numerical reference
exists.
The research API guide explains prompt traces, live observations and the data needed for comparisons. The complete walkthrough connects paired traces, recorded directions, original/zero/intervention controls, text evaluation and CSV/RDS/plot export. It is a repository example: clone or download the repository as well as installing relm.
A separate first-use study records an agent’s actual attempt with the released package. Its six calls completed, but the small model invented facts in every response. Read that report for practical difficulties and what was not tested; it is not external-human usability validation.
llm_generate(async = TRUE) returns a promise while a
native worker generates. on_token receives data-frame
batches of token/text events; on_state receives bounded
live observations. Optional later >= 1.4.8 and
promises >= 1.5.0 are required. In a noninteractive
script, service the event loop until settlement. Callbacks run on R’s
main thread and must remain short; llm_cancel() requests
cooperative cancellation. See the streaming
guide and the complete walkthrough for actual waiting and
cleanup.
Ordinary llm_trace() observes a supplied prompt; it
cannot trace an intervened handle. To compare original and intervened
generation, retain on_state observations and pass them to
llm_compare() with the recorded settings and preceding
sampled-token history. Live coefficient updates are additive; component
projection stays fixed for the derived handle. The support
matrix records the supported combinations.
llm_probe() fits binary ridge models to activation
traces using a formula with activations(). A probe asks how
readily a label can be predicted from internal model values. Explicit
source groups keep related prompts together during cross-validation;
preprocessing and layer/regularization selection use development data
only. Reserve test_groups before analysis for held-out
evaluation and conditional group-bootstrap intervals. Without a holdout,
results are labelled exploratory and carry no inferential interval.
Use summary(), plot() and
predict() on the fitted probe. The anatomy-lab
vignette explains grouped evaluation and saved-fit prediction. The
complete probe
evaluation script runs a paired-source example with paired-label and
simple-feature controls. Predictive decodability does not establish
causal use.
For interventions, llm_steer() adds a chosen direction
to the residual stream, the values passed between model layers.
llm_ablate() fixes selected units to a value to investigate
their effect. Both return a fresh model context over shared weights; the
original handle remains available for an exact reversal. A runtime check
refuses an intervention it cannot verify rather than silently doing
nothing. These are instruments to audit and investigate behavior, not
guarantees of safety or bias removal.
Since 0.2.0, vision-language models accept JPEG, PNG and BMP inputs
through llm_generate(images = ...) and
llm_embed(images = ...). Load the model with its companion
llm(projector = ...): the projector translates images into
values the language model can read. Interpretability of the vision
encoder itself is outside the current release.
Start with these worked demos using pinned Apache-2.0 models:
vignette("anatomy-lab", package = "relm").vignette("topics-without-python", package = "relm").vignette("vision", package = "relm").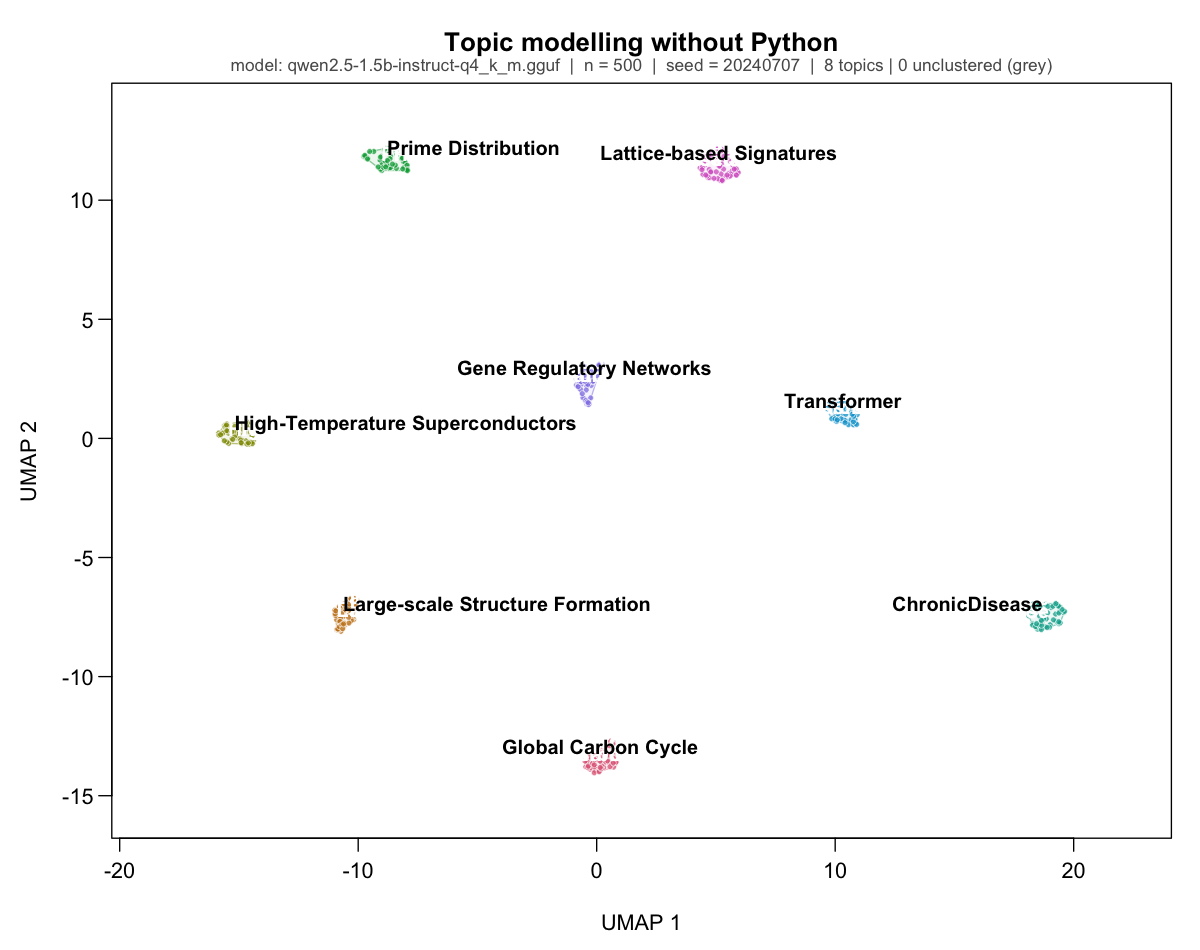
Recorded Demo B output on 500 abstracts. The figure illustrates this corpus and model run; it is not a general clustering-quality benchmark.
The repository includes two application templates, separate from the core API:
Their Mac/Linux operational acceptance includes interruption recovery and 1,000 same-worker service requests. Exact source provenance, limits and prior failures remain in the service report. Operational reliability does not establish extraction accuracy: the frozen D1 pilot had 10/10 schema-valid, 2/10 task-valid and 0/10 fully grounded records, failing all four promotion gates. See the quality evaluation.
The validation ledger distinguishes independent numerical references, regression checks and open hardware/research gates. The architecture and decisions explain the native engine and its boundaries.
Original code is MIT OR Apache-2.0. Vendored llama.cpp is MIT. Modified redistributions must rename under the trademark policy.